Jev projects
Every page in this repo puts measured latency on screen. Typical calls on this machine land in roughly 200 to 1,200 ms, with slower outliers during gateway congestion. Doom Level 3's 50-seed final evaluation had a 260 ms median episode mean and 346 ms median episode p95. A demo that hides this number is a demo of the animation, not of Jev.
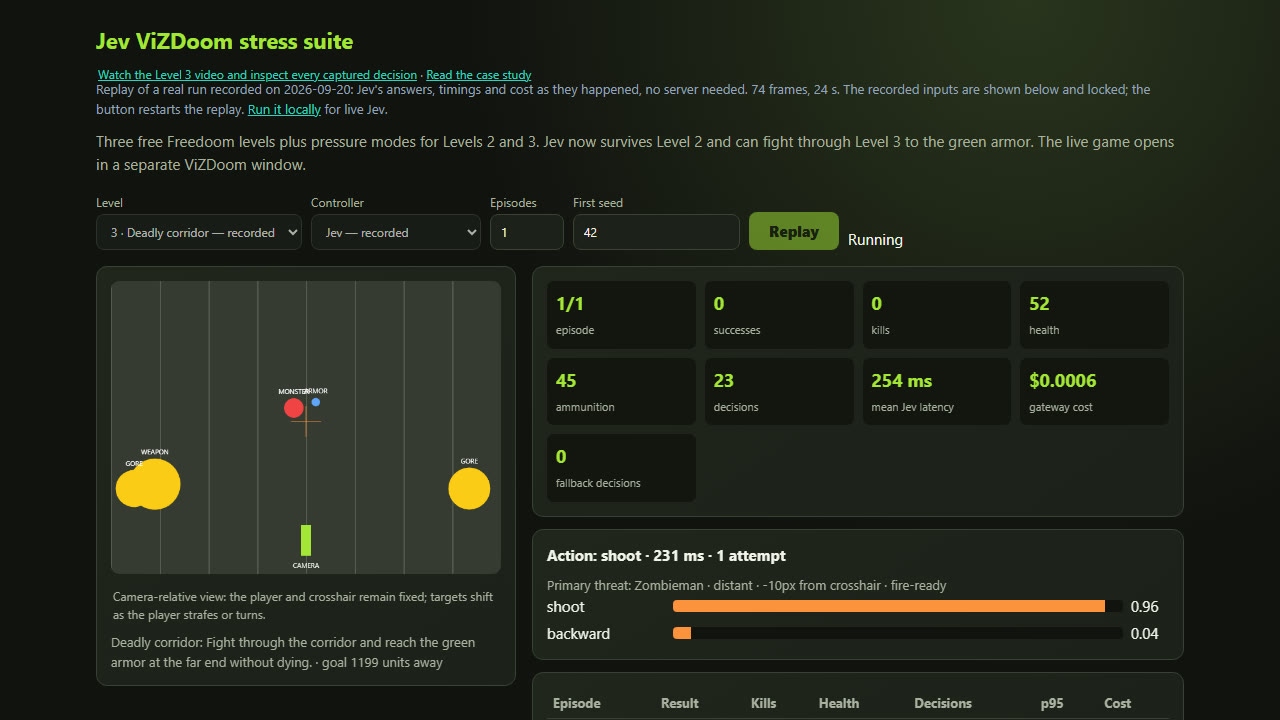
Featured: Jev plays ViZDoom
Aim, survive, handle pressure, then combine combat with navigation. The new Level 3 page pairs a 24-second video with the recorded action, probability, tactical reason and response time.
41/50held-out goals reached
260 msmedian episode mean
346 msmedian episode p95
0final-run fallbacks
Watch the video and inspect the decisions →
Open the interactive replay · Read the case study
What was built: one page per project
Twelve pieces. Eleven use Node directly; Doom uses Python for ViZDoom and a tiny Node worker so it shares the same Jev evaluator. Seven visual projects have an HTML page that polls /state and draws. This site replays measured runs because GitHub Pages cannot hold a gateway key or run the local servers.
| Project | What Jev decides | Loop | Check result |
|---|---|---|---|
probe-burst.mjs | Nothing; 50 boolean calls fired at once | one burst | 48/50 ok, burst 7.8 s, per call min 1,079, median 1,230, max 7,739 ms (the max is the SDK's three retries on a 503) |
wiki/ | Which of up to 255 links on the current Wikipedia page leads to the target | turn-based | 5/5 races Coffee → Napoleon reached it: 4, 7, 5, 7, 4 hops in 4.6, 3.3, 4.8, 5.7, 2.3 s, $0.0004 to $0.0006 each |
town/ | What each of 50 characters does when an event is announced: ignore, investigate, join, flee, warn, plus an urgency score | one burst per event | 50/50 answered, burst 2.7 to 10.0 s, median per call 376 to 643 ms, $0.0011 per event |
chess/ | Which legal move to play (SAN), on a one-minute clock | turn-based | 10 games vs a random mover: 5 checkmates, 5 draws, 0 losses; 572 Jev moves at 465 ms mean; $0.013 |
sort/ | Which of five queues a customer message goes to | 20 calls in flight | 303 labelled messages in 13.8 s, 21.9 items/s, 93.7% agreement with the labels, $0.006 |
logs/ | Severity 0 to 3, page-the-on-call boolean, subsystem, per log line with three lines of context | streamed, 10 in flight | 2,020 lines in 119 s (second run: 573 s, see below), $0.05. Routine max 1.37, incident min 1.47: no overlap. Page boolean fired on 18/20 incidents and 3 routine lines, both runs |
lane/ | Forward, ease left, ease right, brake, or stop, once per tick | ticked, 1,000 ms | 5 runs of 60 ticks: Jev 13 collisions, forward-only 20, rule-based 0. Spec target (fewer than 3) not met |
hooks/skill-router.mjs | Which of 147 Claude Code skills fits the prompt, or none | one call per prompt | 6/6 test prompts matched; 9,920 input tokens, 408 to 6,926 ms, $0.0004 per prompt. A first run saw only 100 skills: 48 skill folders are links and readdir dirents report them as non-directories; fixed with stat |
hooks/verify.mjs | Twelve questions about a git diff in one call | one call per diff | On a synthetic diff: secret 0.99, test_weakened 0.99, debug_left 0.98, unrelated 0.88; risk 2.99 of 3; 340 ms, $0.00003 |
lookback/lookback.mjs | What kind of step each recent Claude Code prompt is (seven kinds) | one call per prompt, 10 in flight | Extractor check passed (free). Live run 2026-10-04: 113 prompts, 20 sessions, $0.0025, 12 decision-type (10.6%). Report |
backlinks/backlinks.mjs | Which other markdown note a note should link to, or none | one call per note | Six synthetic notes: both known pairs linked at p 0.99. Real-folder run not done |
hooks/coding-reflex.mjsWatch the Codex session | Whether a Codex task is incomplete, untested, unsafe or out of scope | one Jev call when Codex stops | Controlled omission: first Stop flagged behavior_untested 0.83 and task_incomplete 0.80 in 1,188 ms; Codex added the direct test; second Stop was clean in 738 ms. Total Jev cost: $0.000198. |
Findings
The gateway and the SDK
- 50 parallel calls mostly work. 48 of 50 returned; two got 503 three times in a row and failed after the SDK's own retries. The median per call in a burst (1,230 ms) is above the sequential range (300 to 700 ms). Sequential runs also see short 503 bursts: the second chess check game died on one.
lib.mjsnow retries four more times at 3, 6, 12, and 24 s. - The SDK rejects a rounding tie. Jev returns probabilities rounded to two decimals. When the chosen option shows 0.13 and another shows 0.14,
ai7.0.107 throwsAI_InvalidResponseDataError: Question "move" did not select a highest-probability option. Chess, with 20 to 40 near-equal options, hits it often.ask()reads Jev's answer from the error'sdatafield and drops the metadata for that call. - 255 options, no more. A 256-option choice is refused with "TypeSafe Choice questions support at most 255 options". Empty-string descriptions are accepted. With 255 fake titles plus "Napoleon Bonaparte" and the target "Napoleon", Jev chose the right one at p 0.97 in 337 ms.
- Cost lives at
providerMetadata.gateway.marketCost, a string in dollars. One boolean call: $0.0000116. One 255-option choice: $0.000177.
What the loops showed
- Batch-and-wait halves throughput. Sorting in batches of 20 ran at 3.5 items/s: every batch waited for its slowest call, and the tail is 5 to 7 s. Twenty workers pulling from one queue ran at 21.9 items/s on the same items.
- Investigate is the town's default. Both "Free bread at the bakery" and "A wolf is at the gate" got investigate as the modal action (36 and 29 of 50). The spread is in the tails: the wolf got 18 warn and 3 flee, the bread 7 join and 3 warn. The check asserts the tails, since the modal test from the spec cannot pass.
- The severity scale is compressed. Only 12 of 20 injected incidents scored above the spec's 2.0 line on the 0 to 3 scale. But no routine line scored above 1.37 and no incident below 1.47, so the sets separate completely at 1.4. The page-the-on-call boolean is the sharper signal: 18 of 20 incidents above 0.5, 3 of 2,000 routine lines above it.
- Jev drives badly from text. Without arithmetic help it collided 29 times in 5 runs of the fixed 60-tick script (17 obstacles). Adding a precomputed
ticks_to_impactper obstacle cut that to 13 to 16. A driver that only goes forward: 20. A rule-based driver with the same information: 0. The check now asserts that Jev beats the forward-only driver. - Jev now clears Doom Level 3 on 82% of held-out seeds. Target locking stopped two enemies from causing left-right oscillation; goal bearing and stuck detection enabled navigation; action masking prevented off-axis shooting. The rule controller reached the armor on 88/100 seeds and Jev on 41/50 final seeds. The tighter two-target-observation corridor remained solvable on 8/10 seeds.
- The gateway has slow hours. The same 2,020-line check took 119 s at about 10:00 local time and 573 s at about 10:30, with 0 failed calls both times and the same separation (routine max 1.38, incident min 1.49). One lane run in that window averaged 8,567 ms per decision against 254 to 568 ms in the others. The 503 retries at 3, 6, 12, and 24 s in
lib.mjskept every answer and paid in wall time. A page that shows latency per call shows this; a page that shows only the animation would not. - Sort accuracy is a rubric question. 88.1% → 87.5% → 93.7% across three rubric versions with Jev unchanged. The remaining misses sit between sales, billing, and other, where the labels (written once by
anthropic/claude-sonnet-5) are themselves one opinion. - Chess: no illegal moves, no losses to random. The options are the legal moves, so the schema does the legality. Five checkmates and five draws; two draws were the 200-ply cap.
Not built
- Minecraft remains unbuilt but is now feasible because Java is installed. Melee needs a legally obtained game image; the trading bot and live Sentry pipeline need external data or accounts. CARLA is unsuitable on the laptop's 4 GiB GPU.
- The wiki race lane against a chat model. Chess against a chat model is wired (a gateway model id in the page's opponent field, 10 s per move) but was not measured.
- The two hooks are written and checked but not installed into
~/.claude/settings.json; each would add 300 to 1,000 ms to every prompt or edit. The README shows the line to add. - The skill router's 30-prompt evaluation against real transcripts. Six hand-written prompts stand in.